Web scraping, the process of extracting data from websites, is a common way to gather financial data from online sources. In Python, each scraping tool fits a different job: requests with BeautifulSoup for static pages, Selenium or Playwright for pages that load data with JavaScript, and Scrapy for large crawls.
Scrapers depend on pages that their owners can change at any time, so they need regular maintenance. When I re-ran this article’s original 2024 examples on November 4, 2026, the Yahoo Finance request came back with HTTP 429 (too many requests), and the Selenium example timed out before the Nasdaq price element appeared. A static Wikipedia table, by contrast, scraped cleanly: 503 S&P 500 constituents, the same 503 tickers that the EODHD Fundamentals API returns for the index.
This guide walks through the whole process, with code that runs today, and shows when a financial data API saves you the maintenance.
Quick jump:
- 1 Choosing a scraping tool in Python
- 2 Define the data and check the rules first
- 3 Analyzing the website structure
- 4 Scraping a static page with Python tools: requests and BeautifulSoup
- 5 Handling dynamic pages with Selenium, a browser scraping tool for Python
- 6 What happened to the 2024 Yahoo Finance example
- 7 Storing and organizing the data
- 8 How to get your EODHD API key
- 9 Getting the same data from an API
- 10 Python scraping tools vs a financial data API
- 11 Conclusion
- 12 FAQs
Choosing a scraping tool in Python
The right Python scraping tool depends on how the page delivers its data and on how much you need to collect.
| Tool | Best for | Notes |
|---|---|---|
| requests + BeautifulSoup | Static HTML pages | Simple and fast. Doesn’t run JavaScript |
| pandas.read_html | Plain HTML tables | One line per table when the HTML is clean |
| Scrapy | Crawling many pages | Built-in scheduling, throttling and export |
| Selenium | Pages rendered with JavaScript | Drives a real browser, slower and heavier |
| Playwright | Pages rendered with JavaScript | Similar to Selenium, with a more modern API |
Start with the lightest option that works. If the data is in the page source (right-click, View page source), requests and BeautifulSoup are enough. If it only appears after the page loads, you need a Python scraping tool that drives a browser.
Define the data and check the rules first
The first step is to define exactly which data you need: prices, company financials, index members, economic indicators. Then find the source and read its rules before writing any code:
- robots.txt (for example https://finance.yahoo.com/robots.txt) lists the paths a site asks automated clients not to visit.
- The terms of service say whether automated collection and reuse of the data are allowed. Many financial sites restrict both.
- Some sites publish an access policy for scripts. Wikimedia, for example, asks scripts to send a descriptive User-Agent with contact information, and may block requests that don’t.
Respect rate limits too. A scraper that sends many requests in a short time can overload a site, and most sites answer with HTTP 429 or block the client.
Analyzing the website structure
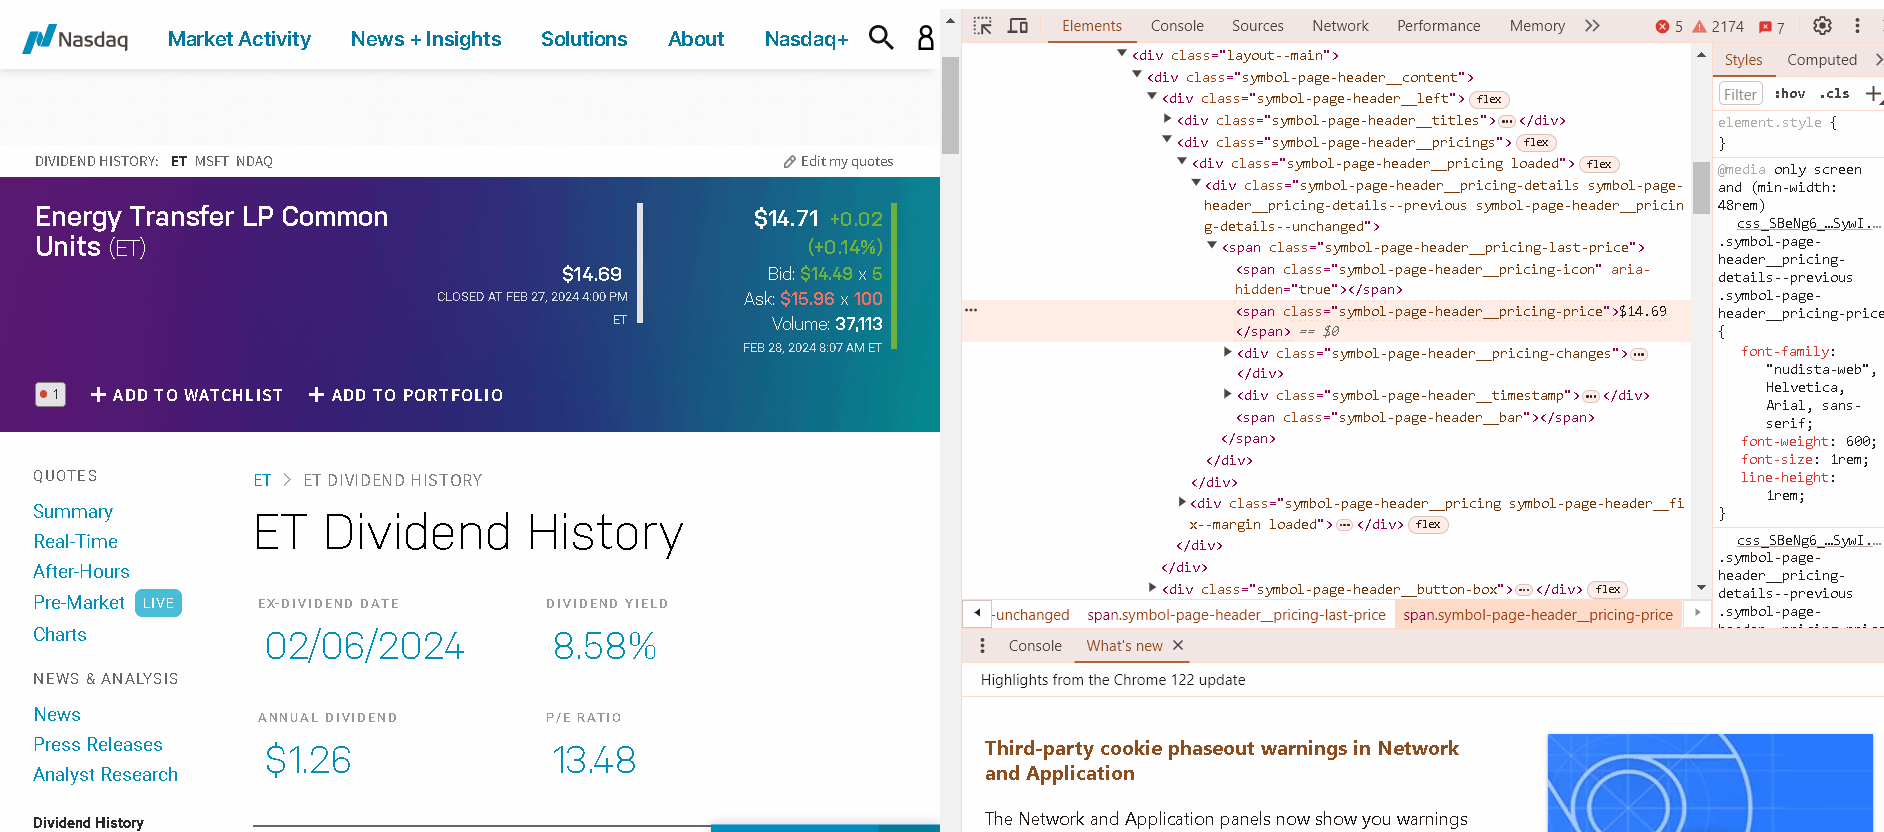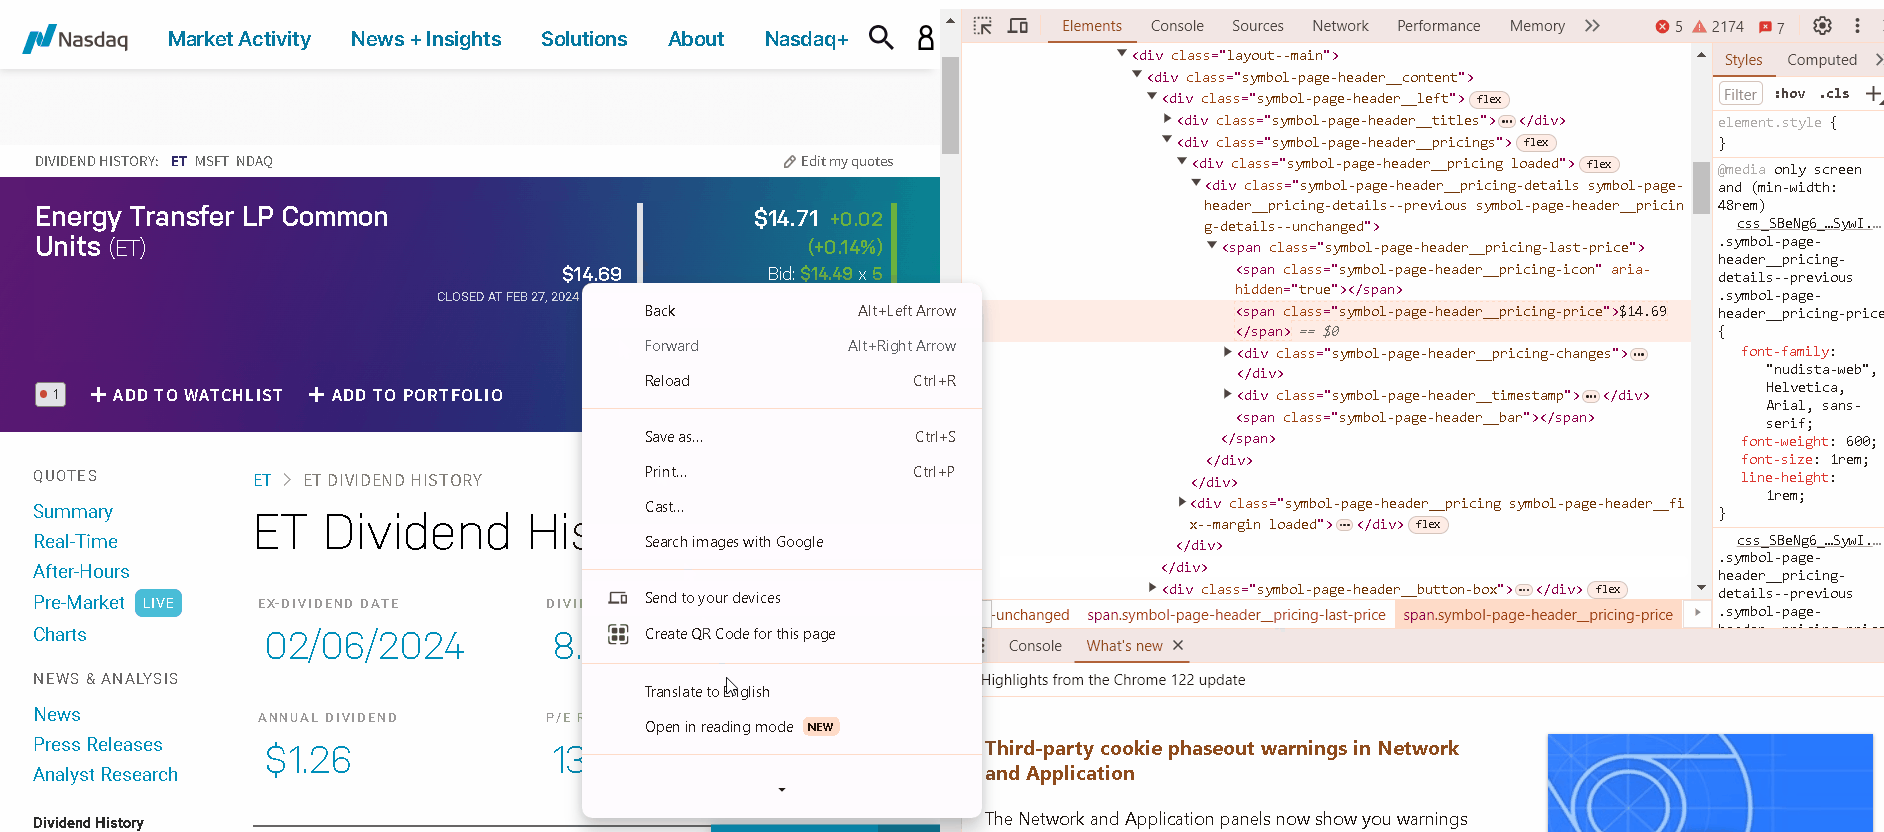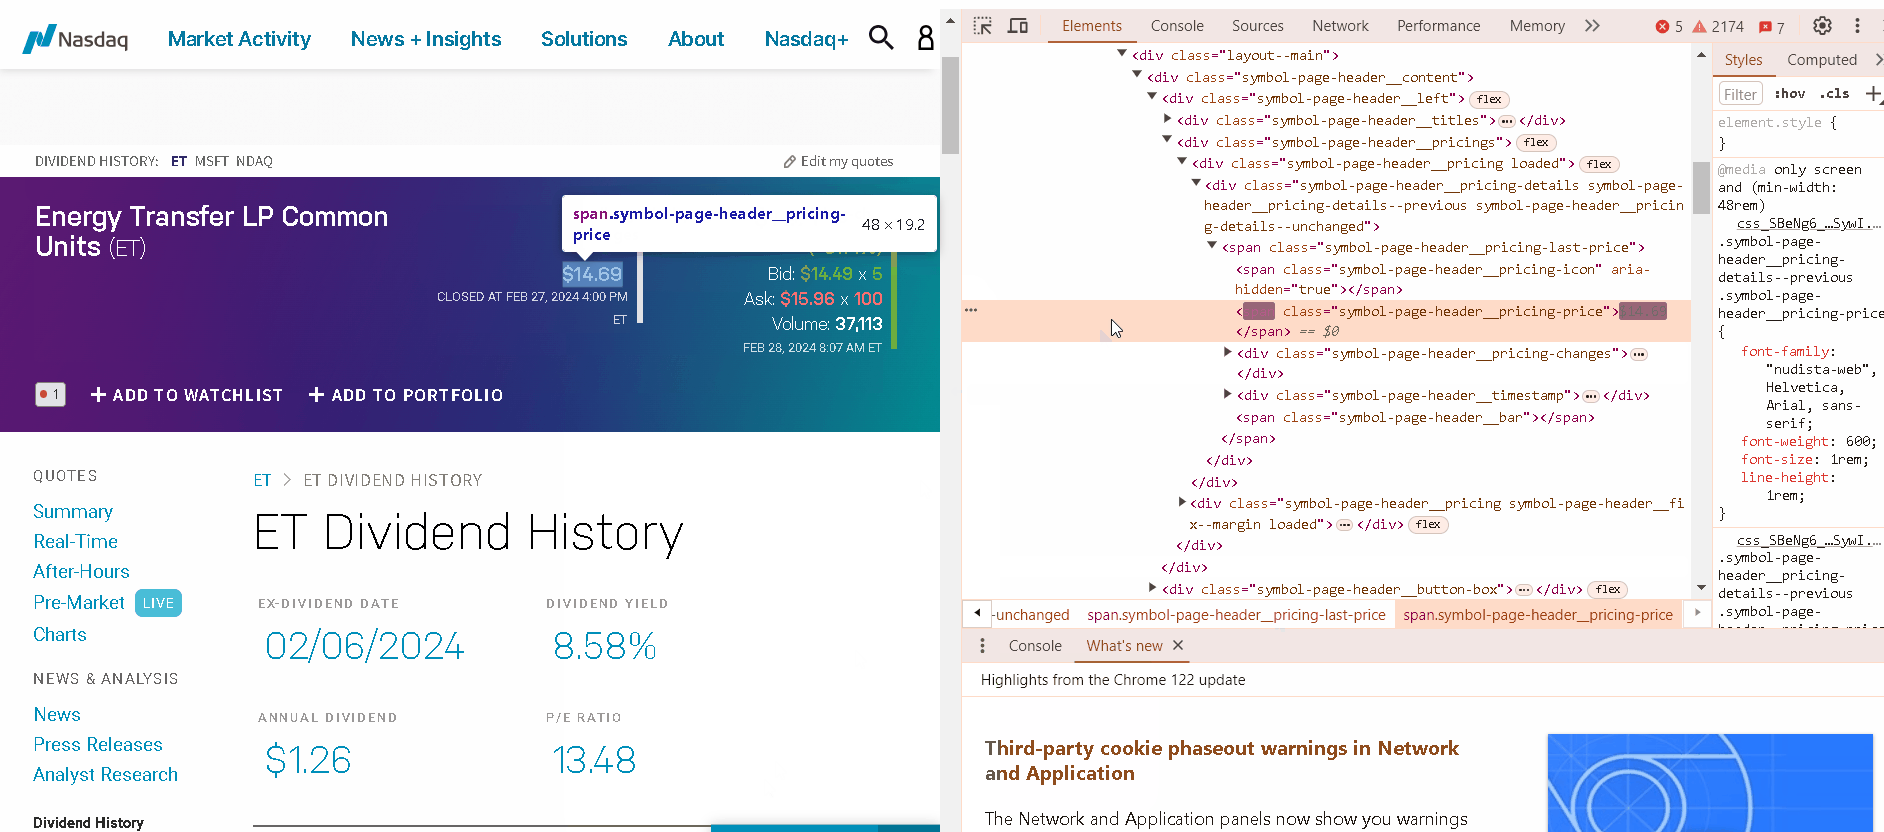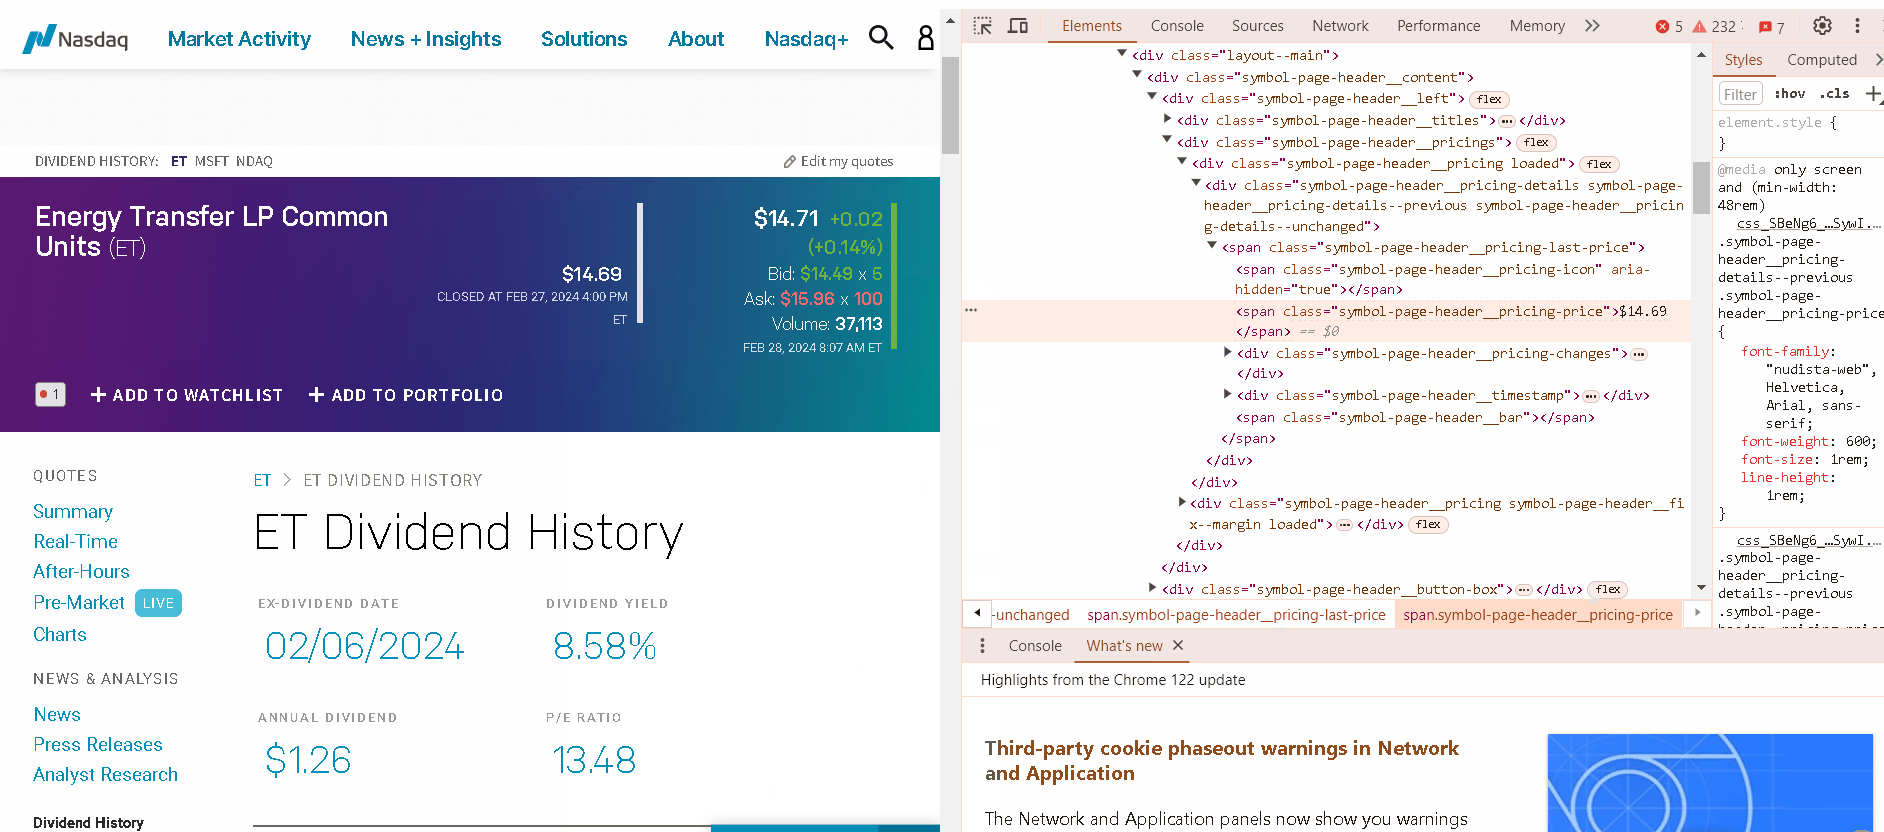
Before writing the scraper, inspect the HTML to find the elements that hold the data. In Chrome, right-click the value you need and select Inspect. Look for stable identifiers, such as an id on a table or a data attribute, rather than generated class names that change with each site release.
Scraping a static page with Python tools: requests and BeautifulSoup
Wikipedia’s List of S&P 500 companies keeps the index members in a table with the id constituents, which makes it a good static example. Install the packages with pip install requests beautifulsoup4 pandas:
import requests
import pandas as pd
from bs4 import BeautifulSoup

URL = "https://en.wikipedia.org/wiki/List_of_S%26P_500_companies"
# Wikimedia asks scripts to identify themselves with a descriptive User-Agent and a contact
HEADERS = {"User-Agent": "sp500-list-example/1.0 (https://example.com; you@example.com)"}

resp = requests.get(URL, headers=HEADERS, timeout=30)
resp.raise_for_status()
soup = BeautifulSoup(resp.text, "html.parser")
table = soup.find("table", {"id": "constituents"})

rows = []
for tr in table.find("tbody").find_all("tr")[1:]:
    cells = [td.get_text(strip=True) for td in tr.find_all("td")]
    rows.append({"symbol": cells[0], "company": cells[1], "sector": cells[2], "added": cells[5]})

df = pd.DataFrame(rows)
df.to_csv("sp500_constituents.csv", index=False)
print(f"{len(df)} rows scraped")
print(df.head().to_string(index=False))
print(df["sector"].value_counts().head(3).to_string())
Replace the User-Agent with your own project name and contact. The output:
503 rows scraped
symbol             company                 sector      added
   MMM                  3M            Industrials 1957-03-04
   AOS         A. O. Smith            Industrials 2017-07-26
   ABT Abbott Laboratories            Health Care 1957-03-04
  ABBV              AbbVie            Health Care 2012-12-31
   ACN           Accenture Information Technology 2011-07-06
sector
Industrials               83
Financials                76
Information Technology    75
The first request I sent with the default python-requests User-Agent returned HTTP 403. With a descriptive User-Agent, as Wikimedia’s policy asks, it returned the full table.
The index has 503 rows rather than 500 because a few companies have two share classes in it. The code depends on the table’s id and on the column order, so if either changes, the scraper stops working or, worse, saves the wrong column.
Handling dynamic pages with Selenium, a browser scraping tool for Python
When a page loads its data with JavaScript, the HTML that requests receives doesn’t contain the values. Selenium drives a real browser, waits for the page to render, and then reads the element. With Selenium 4 (pip install selenium), the browser driver is downloaded automatically, so you no longer need to install ChromeDriver by hand. This is the original article’s Nasdaq example, updated to Selenium 4 and headless mode:
from selenium import webdriver
from selenium.webdriver.common.by import By
from selenium.webdriver.support.ui import WebDriverWait
from selenium.webdriver.support import expected_conditions as EC

options = webdriver.ChromeOptions()
options.add_argument("--headless=new")
driver = webdriver.Chrome(options=options)
driver.get("https://www.nasdaq.com/market-activity/stocks/msft")

def scrape_stock_data():
    try:
        element = WebDriverWait(driver, 15).until(
            EC.visibility_of_element_located((By.CSS_SELECTOR, ".symbol-page-header__pricing-price"))
        )
        return element.text
    except Exception as e:
        return f"{type(e).__name__}: page title was {driver.title!r}"
    finally:
        driver.quit()

print("Stock Price:", scrape_stock_data())
On November 4, 2026, it returned:
Stock Price: TimeoutException: page title was 'www.nasdaq.com'The element the 2024 code waits for didn’t appear within 15 seconds. That is the typical failure of a browser scraper: the code runs, but the page it receives doesn’t have the structure the code expects. Fixing it means inspecting the page again and finding the new selector, and repeating that every time the site changes.
What happened to the 2024 Yahoo Finance example
The original article also read Yahoo Finance’s market capitalization with requests and BeautifulSoup. Run unchanged today, it prints:
Market capitalization of ET: Failed to retrieve data (HTTP 429)HTTP 429 means the server refused the request as too many requests. And even when a page loads, a selector written for a 2024 layout (here a td element with data-test=”MARKET_CAP-value”) is likely to need updating. A scraper built on that kind of markup needs a check that tells you when it stops returning data, rather than printing “not found” and moving on.
Storing and organizing the data
Once the data is extracted, save it in a format that keeps its structure: CSV for tables, JSON for nested data, or a database such as SQLite or PostgreSQL when you collect over time. Store the date you collected each value and its source URL, and validate the values (numbers parsed as numbers, no empty rows) before using them.
How to get your EODHD API key
1. Use the “demo” API key to test our data from a limited set of tickers without registering:
AAPL.US | TSLA.US | VTI.US | AMZN.US | BTC-USD | EUR-USD
Real-Time Data and all of the APIs (except Bulk) are included without API calls limitations with these tickers and the demo key.
2. Register to get your free API key (limited to 20 API calls per day) with access to:
End-Of-Day Historical Data with only the past year for any ticker, and the List of tickers per Exchange.
3. To unlock your API key, we recommend to choose the subscription plan which covers your needs.
The fundamentals requests below (market capitalization and index components) need a plan with fundamentals access, Fundamentals Data Feed or All-In-One, and cost 10 API calls each. With the demo key you can run them for AAPL.US.
Getting the same data from an API
The three values scraped above, a market capitalization, a live stock price and the S&P 500 member list, each come from one EODHD API request:
import os
import requests
import pandas as pd

API_KEY = os.environ.get("EODHD_API_KEY", "demo")
BASE = "https://eodhd.com/api"


def market_cap(ticker):
    params = {"api_token": API_KEY, "fmt": "json", "filter": "Highlights::MarketCapitalization"}
    return requests.get(f"{BASE}/fundamentals/{ticker}", params=params, timeout=60).json()


def live_price(ticker):
    params = {"api_token": API_KEY, "fmt": "json"}
    return requests.get(f"{BASE}/real-time/{ticker}", params=params, timeout=60).json()


def index_components(index):
    params = {"api_token": API_KEY, "fmt": "json", "filter": "Components"}
    data = requests.get(f"{BASE}/fundamentals/{index}", params=params, timeout=60).json()
    return pd.DataFrame(data.values())


print("Market cap of ET.US:", f"{market_cap('ET.US'):,}")

quote = live_price("MSFT.US")
print("MSFT.US:", {k: quote[k] for k in ["timestamp", "close", "change_p"]})

components = index_components("GSPC.INDX")
print(f"S&P 500 components: {len(components)}")
print(components[["Code", "Name", "Sector"]].head().to_string(index=False))
Market cap of ET.US: 69,416,919,040
MSFT.US: {'timestamp': 1793741340, 'close': 520.99, 'change_p': 2.7351}
S&P 500 components: 503
Code Name Sector
AIZ Assurant, Inc. Financial Services
MNST Monster Beverage Corp Consumer Defensive
PGR Progressive Corp Financial Services
CSX CSX Corporation Industrials
ADP Automatic Data Processing Inc TechnologyI ran it with my own API key, since ET.US, MSFT.US and the index components are outside the demo key’s coverage. The timestamp is Unix time: 1793741340 is 21:29 UTC on November 3, 2026, the time of the latest quote in the response. The real-time endpoint returns delayed quotes, not exchange-time ticks.
As a cross-check, I compared the two S&P 500 lists. Wikipedia writes class-share tickers with a dot (BRK.B, BF.B) and EODHD with a hyphen (BRK-B, BF-B). After replacing the dot with a hyphen, all 503 tickers matched.
Python scraping tools vs a financial data API
| Web scraping | Financial data API | |
|---|---|---|
| Setup | Inspect pages, write selectors | Read the documentation, get a key |
| Maintenance | Breaks when the page layout changes | Stable endpoints and documented fields |
| Access rules | robots.txt, terms of service, rate limits per site | Defined by your plan |
| Coverage | One site at a time | Prices, fundamentals, news and more in one format |
| History | Whatever the page shows today | Historical data through the same request |
| Cost | Free to write, paid in maintenance time | Free tier and paid plans |
Scraping still has its place: one-off research, data that no API offers, or pages you own. For data you rely on every day, such as prices, fundamentals or index members, an API removes the selector maintenance and the access-policy risk.
Conclusion
Python makes scraping approachable: requests and BeautifulSoup for static pages, Selenium or Playwright for dynamic ones, Scrapy for large crawls. The hard part comes later, when pages change or limit automated access, as both 2024 examples in this article did.
For financial data you need on a schedule, the EODHD APIs return the same values in a stable format: fundamentals, delayed live prices, index components and more. Try the requests with the demo key on AAPL.US, then move to your own key for other tickers. The EODHD Python Financial Library wraps many of these endpoints in ready-to-use functions.
FAQs
Q: What is the best Python library for web scraping?
For static pages, requests with BeautifulSoup is the simplest Python scraping tool. For pages that load data with JavaScript, use Selenium or Playwright. For crawling many pages with throttling and export built in, use Scrapy.
Q: Is it legal to scrape financial data?
It depends on the site and on how you use the data. Check the site’s robots.txt and terms of service, many of which restrict automated access and reuse of their data. When in doubt, use an official API or a licensed data provider.
Q: Why does my scraper return HTTP 403 or 429?
403 means the server refused the request, often because the client didn’t identify itself or the site doesn’t allow automated access. 429 means too many requests. Follow the site’s access policy, slow down, and consider whether the site permits scraping at all.
Q: Can I scrape stock prices from Yahoo Finance?
Yahoo Finance doesn’t offer an official public API, and its pages change and rate-limit automated requests: this article’s 2024 example now receives HTTP 429. For prices you need regularly, a financial data API such as EODHD’s real-time and end-of-day endpoints is more reliable.
Q: How do I get the list of S&P 500 companies in Python?
You can scrape Wikipedia’s List of S&P 500 companies table with requests and BeautifulSoup, as shown above, or request the GSPC.INDX components from the EODHD Fundamentals API with filter=Components.